Selecting an FM
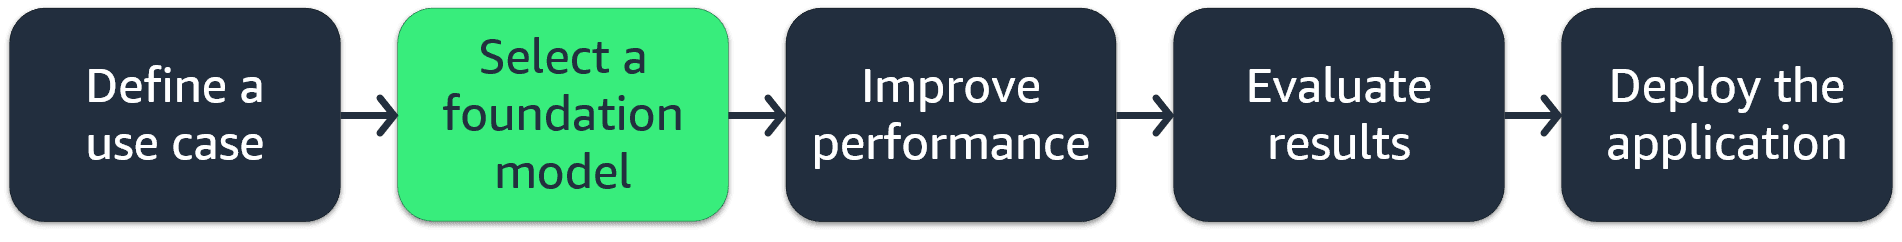
After the use case has been defined, the next phase is the selection of an appropriate foundation model. This choice sets the foundation for the iterative training process and has profound implications for the performance, efficiency, and robustness of the final application. One key consideration is whether to use pre-trained models or develop a model from scratch.
Pre-trained model selection criteria
Pre-trained models offer a valuable head start by encapsulating knowledge distilled from vast amounts of data. These models can be fine-tuned on task-specific data, potentially leading to faster convergence and better generalization. However, pre-trained models might carry undesirable biases or fail to fully capture the nuances of the target domain.
The selection criteria for choosing a pre-trained model depend on the requirements of the business use case.
Some criteria to consider include the following:
Cost
Pre-trained models can be expensive, especially for larger and more complex models. The cost might include licensing fees, computational resources for inference, and potential customization or fine-tuning costs. It's essential to evaluate the budget constraints and weigh the cost against the expected benefits.
Modality
Generative AI models can be designed for different modalities, such as text generation, image generation, audio generation, or multimodal generation (combining multiple modalities). The choice of modality depends on the desired output format and the target application.
Latency
Some applications require real-time or low-latency generation, and others can tolerate longer processing times. The model's inference speed and the available computational resources should be evaluated to ensure acceptable latency for the target use case.
Multi-lingual support
If the application requires generating content in multiple languages, selecting a model that supports the desired languages or can be adapted to new languages through techniques like transfer learning is crucial.
Model size
Larger models generally have higher computational requirements and can be more resource intensive during inference. However, they often perform better on complex tasks. The model size should be balanced against the available computational resources and performance requirements.
Model complexity
More complex models, such as those based on transformer architectures or large language models, can handle more advanced tasks but might be more challenging to deploy and optimize. Simpler models might be preferred for resource-constrained environments or simpler use cases.
Customization
Some pre-trained models offer the ability to fine-tune or adapt them to specific domains or tasks. This customization can improve performance but might require additional computational resources and labeled data.
Input/output length
Generative models might have limitations on the maximum input or output sequence lengths that they can handle. Applications requiring long-form generation or processing of extensive input data should consider models capable of handling the desired input/output lengths.
Responsibility considerations
It's important to evaluate the responsible implications of using pre-trained generative AI models, such as potential biases, misinformation risks, or misuse. Models should be vetted for their training data sources and potential societal impacts.
Deployment and integration
The ease of deployment, compatibility with existing infrastructure, and availability of tools or libraries for integrating the model into the target application should be considered.
It's essential to carefully evaluate these criteria and prioritize the most critical factors based on the specific business use case, including the constraints, and trade-offs involved.
Choosing a pre-trained model based on selection criteria
Comparing pre-trained generative AI models based on selection criteria can be a complex task. There are many factors to consider, and the relative importance of each factor can vary depending on the specific business use case.
To view a few of the pre-trained models available on Amazon Bedrock, select the providers by choosing each of the numbered markers.
2: Amazon
2: Amazon
Titan
Amazon Titan foundation models are a family of models built by Amazon Web Services (AWS) that are pre-trained on large datasets, which makes them powerful, general-purpose models. Use them as is, or customize them by fine tuning the models with your own data for a particular task without annotating large volumes of data.
There are three types of Amazon Titan models: embeddings, text generation, and image generation.
Each of these models could be analyzed for compatibility based on the selection criteria and the business use case. Regularly reviewing and updating the selection criteria as new models and techniques emerge is recommended, because the generative AI landscape is rapidly evolving.
You have completed the lesson on selecting a foundation model. Move on to the next lesson to test your knowledge.