Evaluating an FM
Evaluating foundation model performance
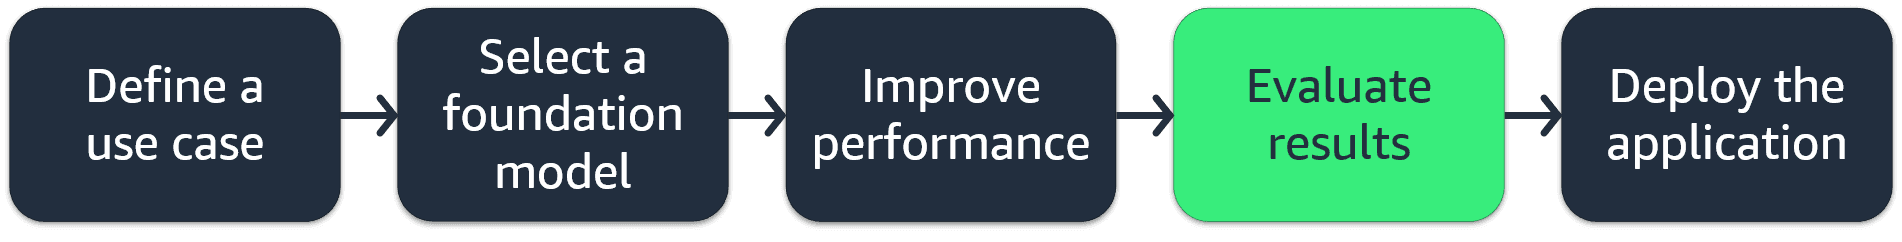
To determine whether a foundation model effectively meets business objectives, it is essential to align the model's capabilities with the specific requirements and goals of the organization.
Types of evaluation methods
Human evaluation:
Human evaluation involves having humans interact with the foundation model and assess its performance based on specific criteria. This can involve tasks such as open-ended conversations, question-answering, text generation, or other specific use cases. Human evaluators can provide qualitative feedback on factors like coherence, relevance, factuality, and overall quality of the model's outputs. Although human evaluation is often considered the gold standard, it can be time consuming and expensive, especially for large-scale evaluations.
Benchmark datasets:
Benchmark datasets are curated collections of data designed specifically for evaluating the performance of language models or other AI systems. These datasets often consist of carefully selected examples or tasks that cover a wide range of topics, complexities, and linguistic phenomena. Models are evaluated by running them on these benchmark datasets and measuring their performance using predefined metrics or tasks.
Some popular benchmark datasets for natural language processing tasks include the following:
- The General Language Understanding Evaluation (GLUE) benchmark is a collection of datasets for evaluating language understanding tasks like text classification, question answering, and natural language inference.
- SuperGLUE is an extension of GLUE with more challenging tasks and a focus on compositional language understanding.
- Stanford Question Answering Dataset (SQuAD) is a dataset for evaluating question-answering capabilities.
- Workshop on Machine Translation (WMT) is a series of datasets and tasks for evaluating machine translation systems.
These benchmark datasets provide a standardized way to compare the performance of different foundation models and track progress over time.
Automated metrics:
Although human evaluation is considered the gold standard, automated metrics can provide a quick and scalable way to evaluate foundation model performance. These metrics typically measure specific aspects of the model's outputs, such as the following:
- Perplexity (a measure of how well the model predicts the next token)
- BLEU score (for evaluating machine translation)
- F1 score (for evaluating classification or entity recognition tasks)
Automated metrics can be useful for rapid iterations and fine-tuning during model development, but they often fail to capture the nuances and complexities of human language and might not align perfectly with human judgments.
Relevant metrics
Metrics like ROUGE, BLEU, and BERTScore provide an initial assessment of the foundation model's capabilities.
- ROUGE
- BLEU
- BERTScore
BERTScore is a metric that evaluates the semantic similarity between a generated text and one or more reference texts. It uses pre-trained Bidirectional Encoder Representations from Transformers (BERT) models to compute contextualized embeddings for the input texts, and then calculates the cosine similarity between them.
These metrics are commonly used to assess the performance of foundation models in generative AI tasks, such as text summarization, machine translation, and open-ended text generation. However, it's important to note that although these metrics provide a quantitative measure of performance, they might not always align perfectly with human judgment. And it's often recommended to combine them with human evaluation for a more comprehensive assessment.
You have completed the lesson on evaluating a foundation model. Move on to the next lesson to test your knowledge.